Fixes
 igv
@@ -1,3 +1,6 @@
|
||||
*checkpoint/
|
||||
params/
|
||||
|
||||
# Byte-compiled / optimized / DLL files
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
|
||||
@@ -2,11 +2,11 @@
|
||||
TensorFlow implementation of the Fast Super-Resolution Convolutional Neural Network (FSRCNN). This implements two models: FSRCNN which is more accurate but slower and FSRCNN-s which is faster but less accurate. Based on this [project](http://mmlab.ie.cuhk.edu.hk/projects/FSRCNN.html).
|
||||
|
||||
## Prerequisites
|
||||
* Python 2.7
|
||||
* TensorFlow
|
||||
* Scipy version > 0.18
|
||||
* Python 3
|
||||
* TensorFlow-gpu >= 1.3
|
||||
* CUDA & cuDNN >= 6.0
|
||||
* h5py
|
||||
* PIL
|
||||
* Pillow
|
||||
|
||||
## Usage
|
||||
For training: `python main.py`
|
||||
@@ -17,7 +17,7 @@ To use FSCRNN-s instead of FSCRNN: `python main.py --fast True`
|
||||
|
||||
Can specify epochs, learning rate, data directory, etc:
|
||||
<br>
|
||||
`python main.py --epochs 10 --learning_rate 0.0001 --data_dir Train`
|
||||
`python main.py --epoch 100 --learning_rate 0.0002 --data_dir Train`
|
||||
<br>
|
||||
Check `main.py` for all the possible flags
|
||||
|
||||
@@ -27,23 +27,26 @@ Also includes script `expand_data.py` which scales and rotates all the images in
|
||||
|
||||
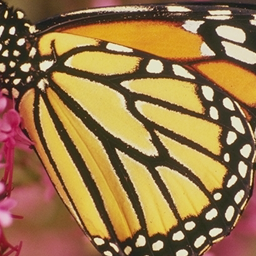
Original butterfly image:
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
Bicubic interpolated image:
|
||||
Ewa_lanczos interpolated image:
|
||||
|
||||

|
||||

|
||||
|
||||
|
||||
Super-resolved image:
|
||||
|
||||

|
||||

|
||||
|
||||
## Additional datasets
|
||||
|
||||
* [General-100](https://drive.google.com/open?id=0B7tU5Pj1dfCMVVdJelZqV0prWnM)
|
||||
|
||||
## TODO
|
||||
|
||||
* Add RGB support (Increase each layer depth to 3)
|
||||
* Speed up pre-processing for large datasets
|
||||
* Set learning rate for deconvolutional layer to 1e-4 (vs 1e-3 for the rest)
|
||||
|
||||
## References
|
||||
|
||||
|
||||

|
Before Width: | Height: | Size: 246 KiB After Width: | Height: | Size: 120 KiB |

|
Before Width: | Height: | Size: 111 KiB After Width: | Height: | Size: 90 KiB |
@@ -13,7 +13,7 @@ def main():
|
||||
print("Missing argument: You must specify a folder with images to expand")
|
||||
return
|
||||
|
||||
for i in xrange(len(data)):
|
||||
for i in range(len(data)):
|
||||
scale(data[i])
|
||||
rotate(data[i])
|
||||
|
||||
@@ -45,4 +45,4 @@ def rotate(file):
|
||||
new_image.save(new_path)
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
main()
|
||||
|
||||
@@ -9,13 +9,13 @@ import os
|
||||
flags = tf.app.flags
|
||||
flags.DEFINE_boolean("fast", False, "Use the fast model (FSRCNN-s) [False]")
|
||||
flags.DEFINE_integer("epoch", 10, "Number of epochs [10]")
|
||||
flags.DEFINE_integer("batch_size", 128, "The size of batch images [128]")
|
||||
flags.DEFINE_integer("batch_size", 32, "The size of batch images [32]")
|
||||
flags.DEFINE_float("learning_rate", 1e-4, "The learning rate of the adam optimizer [1e-4]")
|
||||
flags.DEFINE_integer("c_dim", 1, "Dimension of image color [1]")
|
||||
flags.DEFINE_integer("scale", 3, "The size of scale factor for preprocessing input image [3]")
|
||||
flags.DEFINE_integer("stride", 4, "The size of stride to apply to input image [4]")
|
||||
flags.DEFINE_integer("scale", 2, "The size of scale factor for preprocessing input image [2]")
|
||||
flags.DEFINE_string("checkpoint_dir", "checkpoint", "Name of checkpoint directory [checkpoint]")
|
||||
flags.DEFINE_string("output_dir", "result", "Name of test output directory [result]")
|
||||
flags.DEFINE_string("data_dir", "FastTrain", "Name of data directory to train on [FastTrain]")
|
||||
flags.DEFINE_string("data_dir", "Train", "Name of data directory to train on [FastTrain]")
|
||||
flags.DEFINE_boolean("train", True, "True for training, false for testing [True]")
|
||||
flags.DEFINE_integer("threads", 1, "Number of processes to pre-process data with [1]")
|
||||
flags.DEFINE_boolean("params", False, "Save weight and bias parameters [False]")
|
||||
|
||||
@@ -30,20 +30,22 @@ class FSRCNN(object):
|
||||
self.is_grayscale = (self.c_dim == 1)
|
||||
self.epoch = config.epoch
|
||||
self.scale = config.scale
|
||||
self.stride = config.stride
|
||||
self.batch_size = config.batch_size
|
||||
self.learning_rate = config.learning_rate
|
||||
self.threads = config.threads
|
||||
self.params = config.params
|
||||
|
||||
# Different image/label sub-sizes for different scaling factors x2, x3, x4
|
||||
scale_factors = [[14, 20], [11, 21], [10, 24]]
|
||||
scale_factors = [[24, 40], [18, 42], [16, 48]]
|
||||
self.image_size, self.label_size = scale_factors[self.scale - 2]
|
||||
# Testing uses different strides to ensure sub-images line up correctly
|
||||
if not self.train:
|
||||
self.stride = [10, 7, 6][self.scale - 2]
|
||||
self.stride = [20, 14, 12][self.scale - 2]
|
||||
else:
|
||||
self.stride = [12, 8, 7][self.scale - 2]
|
||||
|
||||
# Different model layer counts and filter sizes for FSRCNN vs FSRCNN-s (fast), (s, d, m) in paper
|
||||
model_params = [[56, 12, 4], [32, 5, 1]]
|
||||
# Different model layer counts and filter sizes for FSRCNN vs FSRCNN-s (fast), (d, s, m) in paper
|
||||
model_params = [[56, 12, 4], [32, 8, 1]]
|
||||
self.model_params = model_params[self.fast]
|
||||
|
||||
self.checkpoint_dir = config.checkpoint_dir
|
||||
@@ -59,21 +61,21 @@ class FSRCNN(object):
|
||||
self.batch = tf.placeholder(tf.int32, shape=[], name='batch')
|
||||
|
||||
# FSCRNN-s (fast) has smaller filters and less layers but can achieve faster performance
|
||||
s, d, m = self.model_params
|
||||
d, s, m = self.model_params
|
||||
|
||||
expand_weight, deconv_weight = 'w{}'.format(m + 3), 'w{}'.format(m + 4)
|
||||
self.weights = {
|
||||
'w1': tf.Variable(tf.random_normal([5, 5, 1, s], stddev=0.0378, dtype=tf.float32), name='w1'),
|
||||
'w2': tf.Variable(tf.random_normal([1, 1, s, d], stddev=0.3536, dtype=tf.float32), name='w2'),
|
||||
expand_weight: tf.Variable(tf.random_normal([1, 1, d, s], stddev=0.189, dtype=tf.float32), name=expand_weight),
|
||||
deconv_weight: tf.Variable(tf.random_normal([9, 9, 1, s], stddev=0.0001, dtype=tf.float32), name=deconv_weight)
|
||||
'w1': tf.Variable(tf.random_normal([5, 5, 1, d], stddev=0.0378, dtype=tf.float32), name='w1'),
|
||||
'w2': tf.Variable(tf.random_normal([1, 1, d, s], stddev=0.3536, dtype=tf.float32), name='w2'),
|
||||
expand_weight: tf.Variable(tf.random_normal([1, 1, s, d], stddev=0.189, dtype=tf.float32), name=expand_weight),
|
||||
deconv_weight: tf.Variable(tf.random_normal([9, 9, 1, d], stddev=0.0001, dtype=tf.float32), name=deconv_weight)
|
||||
}
|
||||
|
||||
expand_bias, deconv_bias = 'b{}'.format(m + 3), 'b{}'.format(m + 4)
|
||||
self.biases = {
|
||||
'b1': tf.Variable(tf.zeros([s]), name='b1'),
|
||||
'b2': tf.Variable(tf.zeros([d]), name='b2'),
|
||||
expand_bias: tf.Variable(tf.zeros([s]), name=expand_bias),
|
||||
'b1': tf.Variable(tf.zeros([d]), name='b1'),
|
||||
'b2': tf.Variable(tf.zeros([s]), name='b2'),
|
||||
expand_bias: tf.Variable(tf.zeros([d]), name=expand_bias),
|
||||
deconv_bias: tf.Variable(tf.zeros([1]), name=deconv_bias)
|
||||
}
|
||||
|
||||
@@ -82,8 +84,8 @@ class FSRCNN(object):
|
||||
# Create the m mapping layers weights/biases
|
||||
for i in range(3, m + 3):
|
||||
weight_name, bias_name = 'w{}'.format(i), 'b{}'.format(i)
|
||||
self.weights[weight_name] = tf.Variable(tf.random_normal([3, 3, d, d], stddev=0.1179, dtype=tf.float32), name=weight_name)
|
||||
self.biases[bias_name] = tf.Variable(tf.zeros([d]), name=bias_name)
|
||||
self.weights[weight_name] = tf.Variable(tf.random_normal([3, 3, s, s], stddev=0.1179, dtype=tf.float32), name=weight_name)
|
||||
self.biases[bias_name] = tf.Variable(tf.zeros([s]), name=bias_name)
|
||||
|
||||
self.pred = self.model()
|
||||
|
||||
@@ -94,9 +96,9 @@ class FSRCNN(object):
|
||||
self.saver = tf.train.Saver()
|
||||
|
||||
def run(self):
|
||||
self.train_op = tf.train.AdamOptimizer().minimize(self.loss)
|
||||
self.train_op = tf.train.AdamOptimizer(self.learning_rate).minimize(self.loss)
|
||||
|
||||
tf.initialize_all_variables().run()
|
||||
tf.global_variables_initializer().run()
|
||||
|
||||
if self.load(self.checkpoint_dir):
|
||||
print(" [*] Load SUCCESS")
|
||||
@@ -104,8 +106,8 @@ class FSRCNN(object):
|
||||
print(" [!] Load failed...")
|
||||
|
||||
if self.params:
|
||||
s, d, m = self.model_params
|
||||
save_params(self.sess, self.weights, self.biases, self.alphas, s, d, m)
|
||||
d, s, m = self.model_params
|
||||
save_params(self.sess, d, s, m)
|
||||
elif self.train:
|
||||
self.run_train()
|
||||
else:
|
||||
@@ -128,11 +130,11 @@ class FSRCNN(object):
|
||||
start_time = time.time()
|
||||
start_average, end_average, counter = 0, 0, 0
|
||||
|
||||
for ep in xrange(self.epoch):
|
||||
for ep in range(self.epoch):
|
||||
# Run by batch images
|
||||
batch_idxs = len(train_data) // self.batch_size
|
||||
batch_average = 0
|
||||
for idx in xrange(0, batch_idxs):
|
||||
for idx in range(0, batch_idxs):
|
||||
batch_images = train_data[idx * self.batch_size : (idx + 1) * self.batch_size]
|
||||
batch_labels = train_label[idx * self.batch_size : (idx + 1) * self.batch_size]
|
||||
|
||||
@@ -178,7 +180,7 @@ class FSRCNN(object):
|
||||
result = self.pred.eval({self.images: test_data, self.labels: test_label, self.batch: nx * ny})
|
||||
print("Took %.3f seconds" % (time.time() - start_time))
|
||||
|
||||
result = merge(result, [nx, ny])
|
||||
result = merge(result, [nx, ny, self.c_dim])
|
||||
result = result.squeeze()
|
||||
image_path = os.path.join(os.getcwd(), self.output_dir)
|
||||
image_path = os.path.join(image_path, "test_image.png")
|
||||
@@ -244,4 +246,4 @@ class FSRCNN(object):
|
||||
self.saver.restore(self.sess, os.path.join(checkpoint_dir, ckpt_name))
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
return False
|
||||
|
||||

|
Before Width: | Height: | Size: 35 KiB |

|
After Width: | Height: | Size: 112 KiB |

|
Before Width: | Height: | Size: 48 KiB After Width: | Height: | Size: 120 KiB |

|
Before Width: | Height: | Size: 42 KiB |